

A company processes 300,000 customer accounts across branches, mobile applications, partner networks and digital channels. Its compliance team tests a sample of transactions, reviews the supporting documents and finds no exceptions. The control passes.
But what if one channel was never included in the test? What if certain transactions never entered the reporting system? Or what if the control worked exactly as designed for the transactions reviewed but was bypassed elsewhere? The test may be correct. The conclusion may not be.
This is a difficult problem in internal controls testing because organizations do not simply need controls that work. They need reliable evidence that those controls are working across the activities they are supposed to cover. As operations grow more distributed, establishing that connection becomes harder.
What does internal controls testing actually prove?
Internal controls testing evaluates whether a control is appropriately designed and operating effectively. A control might require two approvals before a high-value payment, verification before a loan is disbursed, or a review of customer records at defined intervals.Auditors cannot always inspect every transaction manually, nor do they necessarily need to. Sampling is a legitimate audit technique when it is designed around the objective of the test, the characteristics of the population and the level of risk involved. The PCAOB's audit sampling standard explicitly recognizes the risk that conclusions drawn from a sample may differ from conclusions reached by examining the entire population. It also requires sample selection to be appropriate to the audit objective.
The important distinction is between testing a sample and claiming that a control is effective. A sample provides evidence from the items examined. How far that evidence supports a wider conclusion depends on how the population was defined, how the sample was selected, what the test measured and what other evidence is available.
Suppose a lender tests 500 loan disbursements and finds that all 500 contain the required approval. That is useful evidence about those transactions. But it does not, by itself, establish that every eligible disbursement was subject to the control, that the sample represented the wider population, or that transactions outside the sample could not bypass the approval process.
The answer is not to abandon sampling and test everything manually. It is to understand what the test can establish, what it cannot establish, and which additional checks are needed before the organization relies on the result.
The first problem: the organization may not know its full population
Before testing a control, an organization needs to define the population to which it applies. That population is not necessarily every customer in the business. It could be every loan disbursement during a month, every transaction above a specified threshold, every high-risk customer requiring enhanced due diligence, or every AI-assisted decision that requires human review. The population matters because a control cannot be meaningfully assessed without knowing which events should trigger it.Consider a lender that requires additional verification before disbursing loans above a certain threshold. Its compliance team obtains a report of transactions that went through the verification workflow and checks a sample. Every sampled transaction has the necessary documents. There is a problem if the report contains only transactions that entered that workflow. A disbursement that bypassed the workflow entirely may never appear in the report. The control test could find no exceptions because the transactions most relevant to the question were absent from the data being tested.
This is a population-completeness problem, not simply a sample-size problem. Increasing the sample from 500 transactions to 5,000 will not fix a reporting process that systematically excludes transactions from a particular channel.
A more reliable approach begins by establishing the expected population independently of the control's own records. The organization can then reconcile that population against the records of control execution and investigate unexplained gaps. For example, total disbursements recorded in the core lending system can be compared with disbursements that have the required approval evidence. Every eligible transaction should either have the expected evidence or be accounted for through a documented exception. The reconciliation itself must also be tested: if the source system omits a channel or the data feed stops, the apparent completeness of the result can be misleading.
This is why a clean control report is not enough. The organisation must also establish that the report contains the activities the control was intended to cover.
The second problem: the control may work in one part of the business and fail in another
Even when the population is complete, a control may not operate consistently across it. Imagine that a financial services company processes transactions through its mobile application, branch network and third-party partners. The approval control works reliably in the mobile application, but a configuration difference in the partner channel allows certain transactions to proceed without the required approval.
If the test concentrates on mobile transactions, the control may appear effective. The problem is not necessarily that the control was poorly documented or that the sampled transactions were tested incorrectly. The problem is that the control's operation differs across the business. The same pattern can occur across branches, products, customer categories, transaction types, vendors and technology environments. A control that works under one set of conditions may fail under another.
Organizations should therefore examine whether the control is consistently applied across the relevant population, paying particular attention to areas where the process, technology or risk differs. Results can be segmented by channel, branch, product, transaction type and other meaningful characteristics to identify concentrations of exceptions that a single overall pass rate would conceal.
This does not mean every control requires a census of every transaction. It means the testing approach must reflect the way the business actually operates. Where a control is automated and its relevant data is reliable, automated testing across the full transaction population may be feasible. Where a control depends on human judgement, observation, documentation review and risk-based sampling may still be necessary.
The Wolters Kluwer analysis of audit analytics and internal controls testing discusses how data analytics can help organizations test controls against complete transaction datasets where suitable electronic records are available. The practical lesson is that organizations should use population-wide analysis where it provides meaningful additional assurance, rather than assuming either that sampling is always sufficient or that every control must be tested in the same way.
The third problem: the monitoring system may be missing the failures
There is another possibility, and it is often more difficult to recognize. The control may be monitored continuously, the dashboard may show no exceptions, and the underlying process may still be failing because the monitoring system is not receiving all the relevant events.
Suppose a company monitors whether customer transactions receive the required verification. Its dashboard reports zero failures for the month. During the same period, however, a software change disrupts the event feed from one partner channel. Transactions continue to flow, but their verification events no longer reach the monitoring system. The dashboard shows no failures because it cannot see what is happening in that channel. The absence of reported exceptions has been mistaken for evidence that the control is operating effectively.
This is a monitoring-coverage problem. It can affect transaction monitoring, compliance reporting, cybersecurity controls and AI oversight. It is especially consequential when management relies on a central dashboard to understand activity distributed across many systems.
A robust monitoring process therefore needs to assess both the control and the integrity of the monitoring itself. Are expected events arriving? Do source-system transaction counts reconcile with the events evaluated by the monitoring system? Have any channels stopped reporting? Did a configuration or rule change affect which events are assessed? Can the organization identify the period during which coverage was incomplete?
These checks are not administrative extras. They establish whether the monitoring result is trustworthy in the first place. A dashboard showing zero exceptions is useful only when the organization can also demonstrate that the relevant activity was visible to the dashboard.
How can organizations monitor controls across hundreds of thousands of customers?
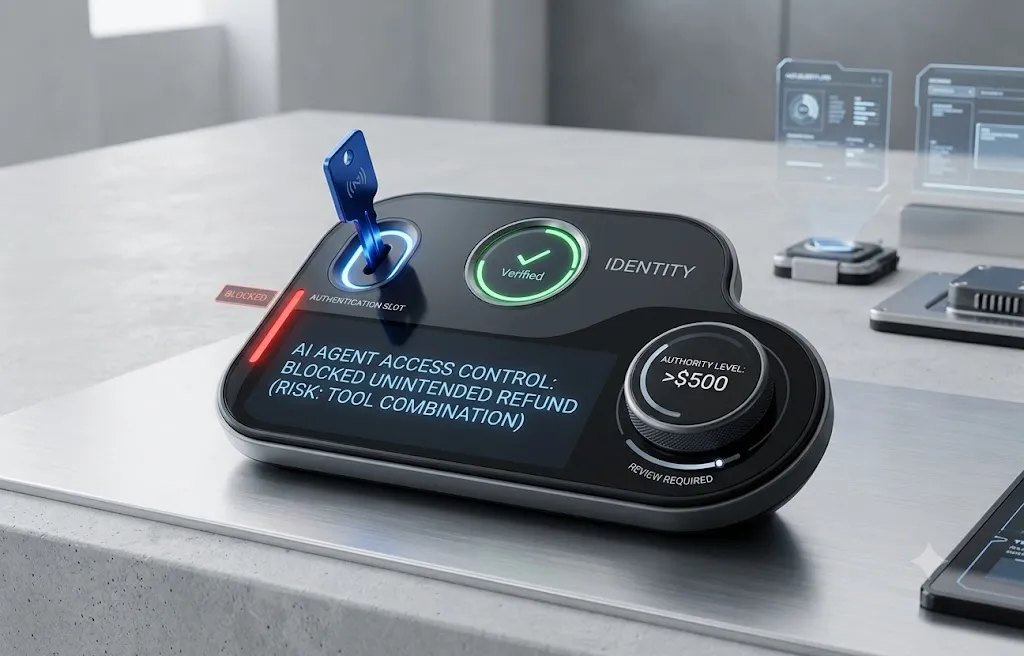
At scale, the answer is not to ask compliance teams to open individual customer records until they have checked every account. It is to combine control enforcement, population-wide monitoring and independent testing, with each serving a different purpose.- Enforce controls as close to the transaction as possible. Where the risk and system design permit, a required approval or verification should be built into the operational workflow. For instance, a disbursement system can prevent an eligible transaction from proceeding until the required approval is recorded. This reduces dependence on discovering the failure later through an audit. Not every control can be enforced automatically. Some require judgement, periodic review or action outside the transaction system. Those controls still need a defined owner, an expected action, supporting evidence and a way to identify when the action has not occurred.
- Monitor the relevant population continuously or at an appropriate frequency. Operational systems should produce data that can be compared against the conditions the control is intended to enforce. The organization can identify transactions with missing approvals, overdue reviews, repeated overrides or other defined exceptions. It can also group these results to reveal whether a problem is isolated or concentrated in a particular channel, product or process. The monitoring logic must reflect the actual control. A missing approval is different from an unusual transaction pattern, and neither automatically proves misconduct. The system should identify a condition that requires investigation, preserve the relevant information and route the issue for appropriate review.
- Independently test whether the monitoring is complete and the control is effective. This includes reconciling source records against monitored events, investigating unexplained gaps, reviewing exceptions and assessing whether the testing approach provides sufficient evidence for the conclusion being made. Sampling remains valuable where appropriate, while full-population testing can be used when the data, control objective and risk justify it.
What happens when a control starts drifting?
Controls are not always static. Business processes change, transaction volumes grow, vendors update their systems, new channels are introduced and teams modify operating procedures. A control that was effective when it was designed may become less effective as the surrounding process changes.This creates a distinction between a control breach and control drift. A breach is an observed failure to meet a defined requirement. Drift is a change in behavior, conditions, configuration or performance that may indicate the control is weakening or no longer operates as intended. For example, a company may require manual review of transactions above a defined risk threshold. A breach occurs when a transaction that requires review proceeds without it. Drift may appear when the number of overrides rises steadily, the proportion of transactions routed for review declines unexpectedly, or a new processing channel begins handling transactions outside the original workflow.
A drift signal is not proof that the control has failed. It is a reason to investigate whether the control's assumptions still hold and whether its operation needs to change. To make this useful, the organization needs to translate each control into observable conditions. It must define what event or state is relevant, where the evidence comes from, how frequently it should be evaluated, what counts as an exception, and who is responsible for responding. If those elements are missing, a monitoring tool cannot reliably determine what to look for or what action should follow.
The response also matters. An exception that sits in a dashboard without an owner, a decision or a remediation record does not create much assurance. The organization needs to track what was investigated, whether the control was found to be deficient, what corrective action was authorized, and what evidence demonstrates that the issue was addressed.
What should an organization be able to prove?
When a regulator, auditor or internal risk committee asks whether a control was effective, a defensible answer requires more than a policy document and a screenshot of a green dashboard.The organization should be able to explain which activities were subject to the control, how it established the completeness of that population, what evidence showed that the control operated, how exceptions were identified and investigated, and what limitations affected the conclusion. Where monitoring was interrupted or the control changed, the organization should be able to establish the impact and show how the gap was addressed.
The strength of the conclusion must match the strength of the evidence. If only a sample was tested, the organization should be able to explain why that sampling approach was appropriate and what other evidence supports the wider conclusion. If part of the population was not visible, that limitation must be acknowledged and resolved rather than hidden behind a passing result.
These are practical questions, not merely documentation requirements. They determine whether an organization can identify a control failure before it becomes a customer complaint, a financial loss, a regulatory finding or a wider operational incident.
Where continuous assurance fits
This is also where organizations need to distinguish operational control systems from the assurance process that sits above them. A lending platform may enforce approvals, a transaction monitoring system may flag unusual activity, and a compliance team may investigate exceptions. Those systems perform essential operational work, but management still needs to understand what changed, which controls may be affected, who is accountable for the response and whether the issue has been resolved with adequate evidence.KlaritiQ's continuous AI assurance approach is built around that broader assurance problem. The intended role is to connect relevant changes and operational signals to defined controls, evidence, accountable owners, remediation work and a record of the resulting decisions. That is an assurance and coordination layer, not a replacement for the systems that enforce transaction rules or detect operational anomalies. The value depends on reliable source data, defined control logic and integrations capable of delivering the necessary signals; it should not be confused with a claim that every customer transaction is already monitored directly by KlaritiQ.
The underlying principle applies well beyond AI. An organization cannot establish that a control is effective simply because a test passed or a dashboard reported no exceptions. It needs evidence that the right population was considered, the control was operating where required, and the monitoring process was capable of detecting the failures it was designed to find.
The most important question is therefore not simply, “Did the control pass?”
It is: “What evidence tells us the control was working across the activities it was supposed to protect, and how would we know if our monitoring had missed a failure?”